Development9 min read
How to measure a two-week AI pilot with useful success metrics
Measure a two-week AI pilot with a baseline, accepted outputs, correction time and escalations, then decide whether to continue, revise or stop.
 By Hamza Ahmad AslamAI & WordPress Developer | Speed Optimization & Site Security
On this page
- Define one task and its AI pilot baseline
- Copyable baseline log
- AI pilot success metrics need clear denominators
- Record handling and correction time for every eligible case
- Empty two-week pilot log
- Illustrative sample rows
- Score accepted outputs, rework and escalations
- Decide continue, revise or stop from the recorded evidence
- What a voice AI pilot should prove
- Use measured pilot work to estimate scaling cost
- Keep the next run measurable
- Frequently asked questions
AI pilot success metrics should tell you whether one bounded task produced acceptable work with less human handling, correction and escalation than its baseline. For a two-week pilot, define one task, measure the current process first, log every eligible case, then apply decision rules written before you see the results.
This protocol evaluates work after you have chosen a task. If you are still deciding where AI belongs, start with AI automation for small businesses before setting up the pilot.
Define one task and its AI pilot baseline
A useful pilot scope is narrow enough that every case can be judged against the same acceptance rule. "Use AI for customer service" is too broad. "Draft a category for each eligible contact-form enquiry for human approval" gives you a unit you can count and review.
Write the scope before changing the workflow:
| Scope field | What to record |
|---|---|
| Task | The single repeated job being tested |
| Trigger | What creates an eligible case |
| Eligible case | The exact cases included in the pilot |
| Exclusions | Cases that must stay outside the AI path |
| Required output | What the AI-assisted step must produce |
| Acceptance rule | What a reviewer must see before accepting the output |
| Reviewer | Who makes the acceptance decision |
| Escalation rule | When the case returns to a person or existing process |
| Stop condition | An outcome that ends or pauses the test regardless of averages |
| Version | The model, prompt, workflow and relevant configuration under evaluation |
If the workflow needs a WordPress-specific data source, admin screen or integration, define that boundary before development. A custom WordPress plugin development project may supply the integration, but the pilot should still evaluate one business task rather than the whole plugin.
The baseline is the same task before the AI change. Record human handling time, whether the completed work needed rework, and whether it had to move to another person or process.
Use the same eligibility rule during the baseline and pilot. Otherwise you can make the pilot appear faster by giving it easier work.
Copyable baseline log
Copy one row for each baseline case. Do not fill missing measurements with estimates.
| Case ID | Date | Case type | Human handling minutes | Rework needed? | Escalated? | Notes |
|---|---|---|---|---|---|---|
Your AI pilot baseline does not need to match the pilot's calendar length. It does need to represent the same task under conditions you can compare. If you cannot produce a usable baseline, record that limitation and avoid claiming a time saving.
AI pilot success metrics need clear denominators
Start with accepted work. An accepted output is one that meets the written acceptance rule after review.
Separate three outcomes. "Accepted without correction" means the reviewer made no substantive change. "Accepted after correction" means a person had to repair the output before it met the rule. "Escalated" means the case left the AI path and moved to the defined fallback.
That distinction matters because a workflow can produce many usable drafts while creating enough editing work to erase the handling-time benefit.
Use these formulas consistently:
| Metric | Formula | What it tells you |
|---|---|---|
| Baseline human minutes per case | Baseline human minutes / baseline eligible cases | Current human effort |
| Accepted output rate | Accepted outputs / AI outputs reviewed | How often reviewed output reaches the acceptance rule |
| Accepted without correction rate | Outputs accepted unchanged / AI outputs reviewed | How often review finishes without rework |
| AI pilot rework rate | Outputs accepted after correction / AI outputs reviewed | How often an AI output needs repair |
| Escalation rate | Escalated cases / pilot eligible cases | How much work leaves the AI path |
| Pilot human minutes per case | Review + correction + escalation handling minutes / pilot eligible cases | Human effort after adding AI |
| Human time delta per case | Baseline human minutes per case - pilot human minutes per case | Direction and size of the handling-time change |
Keep counts beside rates. The denominator should remain visible when someone reviews the pilot later.
An escalation is not automatically a bad result. If the scope says an ambiguous request must go to a person, a correct escalation is the expected outcome. Record unnecessary escalations separately from required ones if that distinction matters to the task.
NIST's AI Risk Management Framework (opens in a new tab) is intended for voluntary use and includes evaluation as part of managing AI risk. Its AI RMF Playbook (opens in a new tab) groups its guidance under Govern, Map, Measure and Manage. For this pilot, use that broader risk work as context while keeping the operational scorecard tied to the task you are testing.
Record handling and correction time for every eligible case
Do not measure only the time spent generating an answer. Human review, editing and manual fallback are work created or retained by the pilot.
Keep review and correction time separate. Review time is the time needed to inspect the proposed output and make a decision. Correction time starts when the reviewer has decided that the output needs changes.
For an escalation, record the human time spent completing or routing the case after it leaves the AI path. That keeps difficult cases inside the workload calculation.
Empty two-week pilot log
Use one row for every eligible case during the two-week observation window. Duplicate rows as needed.
| Case ID | Date | Case type | AI output reviewed? | Review min | Correction min | Escalation/manual min | Final result | Correction category | Escalation reason | Stop condition? |
|---|---|---|---|---|---|---|---|---|---|---|
The two-week window is the boundary for this protocol, not a universal AI pilot duration. If the task occurs too rarely to cover its normal case types, extend the observation period rather than adding unrelated work just to increase the count.
Illustrative sample rows
Every name, case and number below is illustrative. They show how to fill the log and do not report a measured pilot.
| Case ID | Case type | AI output reviewed? | Review min | Correction min | Escalation/manual min | Final result | Correction category | Escalation reason | Stop condition? |
|---|---|---|---|---|---|---|---|---|---|
| Illustrative A | Illustrative standard enquiry | Yes | 2 | 0 | 0 | Accepted without correction | None | None | No |
| Illustrative B | Illustrative incomplete enquiry | Yes | 2 | 4 | 0 | Accepted after correction | Missing detail | None | No |
| Illustrative C | Illustrative out-of-scope request | Yes | 1 | 0 | 7 | Escalated | None | Outside pilot scope | No |
These rows should not become target values. Set your thresholds from the task, baseline and consequence of a wrong output.
If the pilot runs through n8n, distinguish a business case from a technical run. n8n defines an execution as one run of a workflow (opens in a new tab), so retries or other workflow behavior can make execution counts differ from eligible business cases.
On n8n plans that include it (Cloud Pro or Enterprise, or self-hosted Enterprise or registered Community), custom execution data (opens in a new tab) can be stored with executions and used when filtering them. A case identifier or review state can help connect technical records to the pilot log, but the reviewer still needs to record the final business outcome.
Score accepted outputs, rework and escalations
Set the thresholds before the final AI pilot evaluation. There is no useful universal percentage for acceptable rework or escalation because the cost of an error differs by task.
Your scoring sheet should therefore contain your thresholds, not somebody else's benchmark.
| Signal | Your threshold | Pilot observation | Decision effect |
|---|---|---|---|
| Accepted output rate | Check whether the task reaches its acceptance rule often enough | ||
| Accepted without correction rate | Shows how much work ends at review | ||
| Rework rate | Shows how much editing the AI path creates | ||
| Escalation rate | Shows how much work returns to a person | ||
| Pilot human minutes per case | Compare with the baseline | ||
| Stop conditions | None permitted unless explicitly defined otherwise | Apply before average scores | |
| Case coverage | Confirm the pilot included the case types the decision depends on |
A good AI pilot success metric sits close to accepted business work. For a drafting or classification task, accepted outputs plus human minutes usually tell you more than raw model output volume.
AI pilot KPIs should also stay separate when they answer different questions. A lower handling time cannot cancel a failure that your scope defined as unacceptable. A good acceptance rate cannot hide a correction category that keeps repeating.
Decide continue, revise or stop from the recorded evidence
Apply the decision rules in the same order every time:
| Step | Observation | Decision |
|---|---|---|
| Stop conditions | A predeclared stop condition occurred | Stop or pause the affected path before considering averages |
| Acceptance | Acceptance and quality thresholds are met | Continue to the time and escalation checks |
| Acceptance | Threshold is missed and the misses cluster around a defined, repairable cause | Revise, version the change and rerun the affected cases |
| Human effort | Pilot human minutes per case meet the target against the baseline | Supports continuing within the tested scope |
| Human effort | Review or correction work misses the target but has a specific repair path | Revise and measure again |
| Escalations | Escalations match the allowed scope and threshold | Supports continuing |
| Escalations | Excess escalations come from a defined input, prompt, rule or integration issue | Revise before expansion |
| Evidence quality | The baseline, eligibility rule or case coverage cannot support the comparison | Revise the measurement and rerun |
| Core task fit | The workflow still cannot meet its acceptance or effort requirement after the planned revision | Stop the pilot rather than expanding it |
"Continue" means continue only within the boundary you measured. It does not prove that a different department, customer group or task will produce the same result.
"Revise" means make a named change and create a new version. Do not mix results from materially different prompts, models or workflow logic into one score and call it a single trial.
"Stop" can be a useful result. It prevents a larger implementation from being justified by a demo that never met the operating requirement.
What a voice AI pilot should prove
A voice AI pilot uses the same accepted-work and human-effort test, with channel-specific acceptance rules.
Define which facts the call must capture, which request types it may handle, and when it must transfer to a person. Then record whether each eligible call reached an accepted outcome, needed correction after review, or entered the handoff path.
Include the records a reviewer needs to judge the case. A smooth-sounding call is not enough evidence if you cannot determine whether the required task was completed correctly.
Keep the pilot bounded to the voice task. Broader questions about chatbot interfaces, lead routing or generated replies belong in separate tests.
Use measured pilot work to estimate scaling cost
Do not turn a short pilot into an annual savings claim by multiplying an assumed number of minutes across future volume.
Instead, carry forward what you measured: eligible case volume, review time, correction time, escalation work and the proportion of outputs that reached acceptance. Use those values with the AI workflow costs worksheet to model what the workflow would cost at a larger volume.
That separates two decisions. This pilot asks whether the work is acceptable and how much human effort remains. The cost worksheet asks whether operating that workload makes financial sense at the planned scale.
Keep the next run measurable
Save the scope, baseline, empty log, completed log, formulas, thresholds and exact workflow version together. If you revise the system, start a new result set rather than overwriting the evidence that led to the change.
If the workflow continues beyond the pilot, keep recording failures and missed work instead of relying on the two-week sheet as permanent proof. The guide to monitoring failed AI workflows and recovering missed work covers that operating phase.
Frequently asked questions
How many cases should an AI pilot include?
There is no universal case count for this protocol. Include every eligible case during the chosen observation window when practical, report the count, and state which normal and difficult case types were represented.
Should human review time count when measuring AI time savings?
Yes. Count review, correction and manual fallback work before comparing pilot human time with the baseline. Ignoring review work can make a workflow appear to save labor by moving that labor to a different step.
What if I did not measure a baseline before starting the AI pilot?
Record the pilot's quality, correction and escalation results, but do not claim a measured handling-time improvement without a comparable baseline. You can establish the baseline before a later pilot run and then make the comparison.
Does an escalation mean the AI pilot failed?
Not when escalation is the planned outcome for a case outside the AI path or beyond its allowed authority. Measure expected and unnecessary escalations separately if both can occur, and judge the rate against the threshold you set before the final review.
How this article was made: drafted with AI assistance from a researched brief, then checked against primary documentation before publishing.
Share this article
Enjoyed this? Get the next article by email.
Keep reading
 Development
9 min read
Gemini 4 Carbon review: Google's claims, independent results and what testers found
Gemini 4 Carbon, often searched as Google Carbon, is Google DeepMind's newest top model. Google announced it on 28 October 2026 for a small group of security teams, then made it generally available on 10 November 2026. It is built on Gemini 4 Argon, which stays on sale beside it.
- AI
- Integration
- Automation
 Development
8 min read
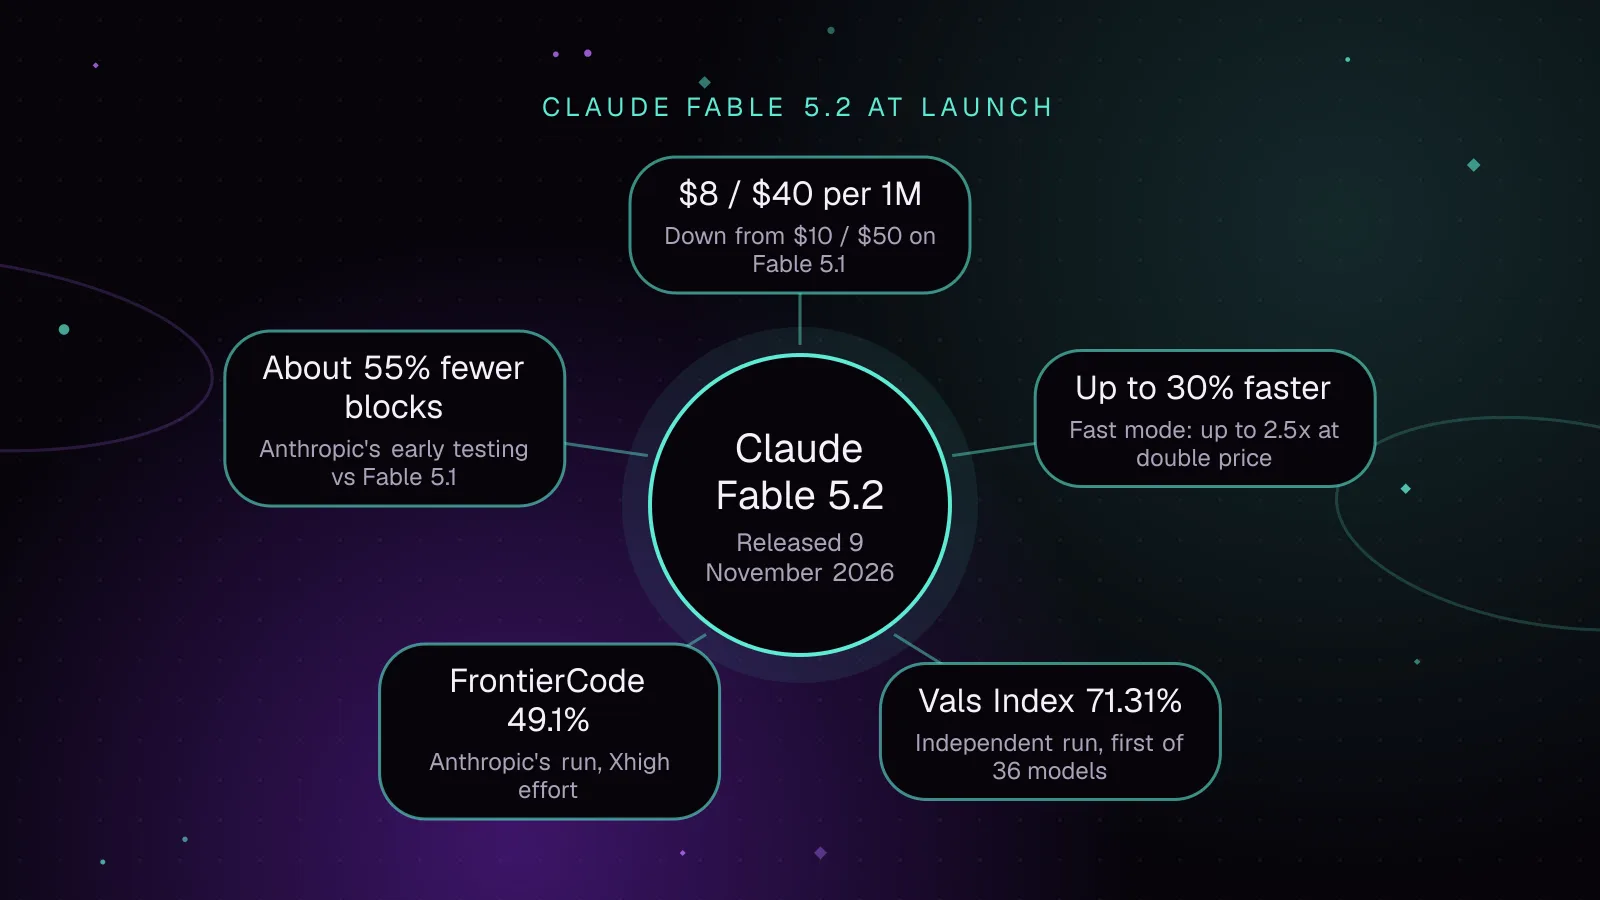
Claude Fable 5.2: benchmarks, price and the first independent test results
Claude Fable 5.2 is Anthropic's newest top model, released on Monday, 9 November 2026, alongside a restricted sibling called Claude Mythos 5.2.
- AI
- Integration
- Automation
 Development
8 min read
AI automation cost for small business: a workflow worksheet
To estimate AI automation cost for a small business, price one workflow in four layers: setup, recurring cash charges, usage and retries, and staff time for review and maintenance. Then divide the full monthly operating cost by accepted results and compare it with the manual cost of the same volume.
- AI
- Automation
- Small Business